Transform PDFs into Markdown
One API call turns a PDF into Markdown, including tables, multi-column layouts and scanned pages. It runs on Docling, hosted for you.
No credit card required
const res = await fetch('https://api.parsebridge.com/v1/parse/url', {
  method: 'POST',
  headers: {
    'Authorization': 'Bearer YOUR_API_KEY',
    'Content-Type': 'application/json'
  },
  body: JSON.stringify({
    url: 'https://parsebridge.com/downloads/docling/ocr/scanned-order.pdf'
  })
});

const { content } = await res.json();content1 page · 1 credit| Item | Quantity | Amount | |-----------------|------------|-----------| | Archive folders | 3 | CHF 18.00 | | Storage boxes | 2 | CHF 24.00 |
A scanned order form, converted
A scanned PDF with no text layer. Text recovered with OCR; item rows preserved as a Markdown table.
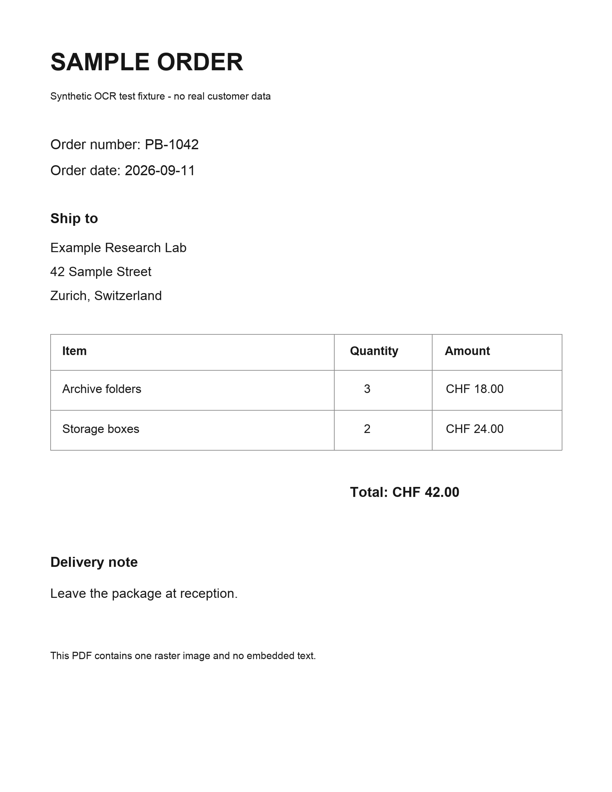
## SAMPLE ORDER
Synthetic OCR test fixture - no real customer data
Order number: PB-1042
Order date: 2026-09-11
## Ship to
Example Research Lab 42 Sample Street Zurich, Switzerland
| Item            |   Quantity | Amount    |
|-----------------|------------|-----------|
| Archive folders |          3 | CHF 18.00 |
| Storage boxes   |          2 | CHF 24.00 |
Total:
CHF 42.00
## Delivery note
Leave the package at reception.
This PDF contains one raster image and no embedded text.Drag to compare
Synthetic sample data, not a customer document. The output is copied unedited from Parsebridge, including what it got wrong: the three address lines were joined into one paragraph, and the total label and amount became two paragraphs.
See it on your own document
Paste a PDF URL or upload a PDF to get a live Markdown preview. No account needed.
Preview mode parses page 1 only
Page 1 Markdown will appear here
Parsing that gets the hard parts right
Tables, layouts, and scanned pages. The stuff that breaks other parsers. One API call, clean Markdown out.
Table & layout extraction
Tables and multi-column layouts keep their structure
Merged cells, nested headers, multi-column layouts. The stuff that usually comes back garbled. We turn it into structured Markdown you can actually use.
Documents aren't kept
PDFs are deleted when the request finishes
Uploads are stored only while they're converted, then deleted, and the Markdown isn't saved. We keep request metadata such as file name, page count and timing to run the service and track usage.
Built for volume
Up to 300,000 pages per month on one plan
Each request goes to the least busy parsing engine and fails over if one is down. Long documents can take a few minutes.
Pick a monthly page volume
One credit is one page. Credits refresh monthly and unused ones don't roll over.
Basic
$17/mo
Perfect for startups and small projects
5,000
pages per month · $3.40 per 1,000 pages
GrowthMost popular
$79/mo
For growing businesses with regular document processing needs
60,000
pages per month · $1.32 per 1,000 pages
Scale
$259/mo
For enterprises processing documents at scale
300,000
pages per month · $0.86 per 1,000 pages
- API key management
- Usage analytics
- Premium support
- 50 free pages to start
Questions before you commit? support@parsebridge.com
Frequently asked questions
If you can't find what you're looking for, reach out to our support team and we'll be happy to help.
Currently, Parsebridge API supports PDF files only. We focus on providing the best possible extraction quality for PDF documents.
Credits are calculated based on the number of pages in your PDF. 1 credit = 1 page. You only pay for what you process.
If you run out of credits, API requests will return an error and we will alert you. You can upgrade your plan or wait for your monthly credits to refresh.
Yes, PDFs can be up to 50 MB each. For larger files, consider splitting them or contact support for enterprise solutions.
Yes. Every new account gets 50 free credits to test our service. No credit card required for the trial.
No, unused credits do not roll over to the next month. Each billing cycle starts fresh with your plan's credit allocation.
Under the hood, we use Docling, an open-source parser known for its table extraction and layout preservation. We handle the infrastructure, OCR, scaling, and API layer on top so you don't have to.
We parse the content with formatting like Markdown supports it. Images are referenced as Markdown comments.
Yes, we only store the data until we give you a response. We do not keep the content.
Yes, you can cancel your subscription at any time. You'll retain access until the end of your current billing period.
Integrations
Use Parsebridge from your existing automation tools.